
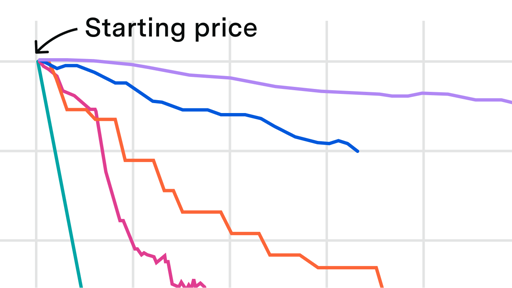
The cost decline for a given level of performance does tend to slow over time
Even in their tests, there are big drops in 2026 models, and recent ones.
Opus 4.8 (may 2026), by far best model at the time, gets equaled by deepseek 4 pro (july 31) and 4.1 flash (sept 10th) at less than 1/100th the cost. MiMo 2.6 pro (sept 21) is even cheaper and beats opus 4.8 scores by a wide margin. sonnet 4.6 max to gpt luna high is also a 99% drop in a short time for lower performance models.
The other day I saw a video talking about this new innovation on LLM inference side of things where they keep some more used weights in RAM and others less used on disk. I always suspected from the sample code I stumbled upon on the IA world that should be extreme opportunities for optimizations. But I cannot stress it enough how dumb the LLM world is where the basics of implementing an LRU cache is pass of as some big innovation. Like any half competent comp-sci or comp-eng professional know about the basics of mitigating this basics bottlenecks like “the data does not fit on available RAM”, “The disk is slow”, etc.
So is not surprising that now that it seems that the “powerfulness” of this LLMs is starting to plateau that we would start to see some improvement in performance/resource utilization and hence running costs.
That works for “Mixture of Experts” models. These are basically models with distinct sets of weights and only a subset of them will be used on any particular query. The rest can sit on a disk.
It doesn’t work for dense models, where every weight is used all the time. There’s nothing inactive so a cache has nothing to exploit.
Moore’s Law hasn’t been applicable for years.
I forsee a future for LLMs which is where the only people who will be using it is where they HAVE to use it. When it’s the only reasonable tool for the job. And it will be expensive and unprofitable to run.
It has some use cases, but they are few. The market can’t support what they’re people want LLMs to be
Thanks in part to China who release a lot of research free.
All that R&D, and they need to squeeze efficiency out more at this stage. Faster and more specialized is better than big chingus do everything, and means we can hopefully stop spending all that money on making more datacenters.
Personally, I don’t use the big chingus models at all… I much prefer local gen if I use it for things. Much better privacy that way, and I’m not throwing money at these jokers.
Are there some local models that one can use that are not giving our data away and on par with chat GBT?
I wonder how they plan to match “prices are in free fall” to “the AI industry will have to make trillions a year in order not to go bust”.
On the other hand, “prices in free fall” might be the answer they got from AI…
At this point the cloud model firms are basically banking on making a superinteligence before anyone else and taking over the planet, otherwise they go bankrupt. I wish I was kidding.
Nvidia wins either way though, local models, cloud models, shovels always sell. So they have that overvalued but still realistic bedrock to build houses of cards on.
Yeah, OpenAI released Astra just a couple of weeks ago, then around last week they released Sol 6, which is around half the price of Astra. So you have around the same level of “reasoning” at half the price. They will never turn a profit, at least for the next several years or so.
So revenue is falling. The only way the bubble grows is forcing this shit into even more places?
the price of thought
Oh fuck off.
No actual thought here in this comment
These fuckers would sell us air if they could.
That’s cool and all, but when can I buy RAM again?
In 4 years or never. The latter probably being the most likely, since they are not just keeping RAM from you for AI purposes. They don’t want you to own you own hardware anymore, so they just simply stop manufacturing consumergrade hardware.
They don’t want you to own [your] own hardware anymore
Daily, it seems, I realize I’m one of the non-telepathic people: I can’t immediately know chip-maker company CEO motives and goals, and I just don’t see the conspiracy you do. What am I thinking right now?
Probably not never - CXMT are trying to aggressively expand to fill the market now the major players have left, but it will still be a few years before prices really come down as a result.
Kinda sus that the cost of electricity stops at 1973.
“Look how low our cost of inference is”
“Pay no attention to the marketing budget that exceeds Coca-Cola’s for a small fraction of their revenues”
What technical, fundamental reason is there for the crash in price? The article just accepts the MSRP as fact. The cost of training can indeed be spread over time but it’s not spread across enough time. The inference cost doesn’t actually drop in reality.
Let’s just quickly check https://isaiprofitable.com/ :
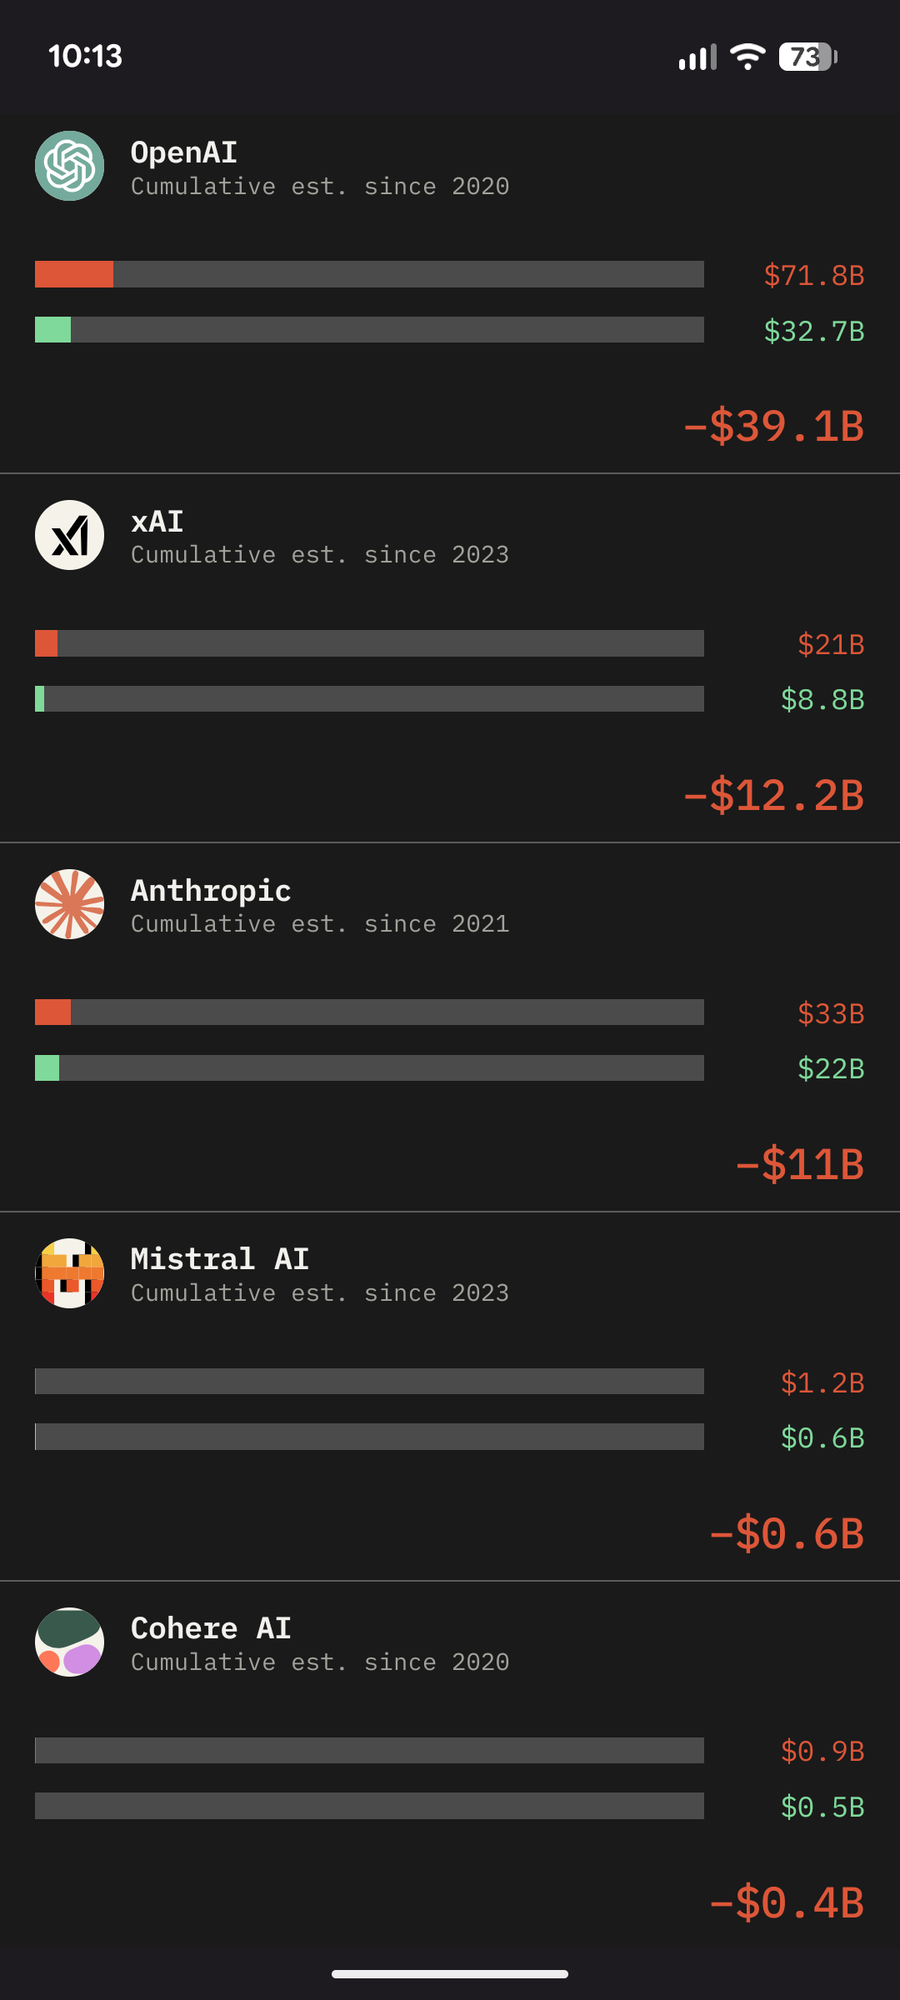
Nope. The answer is still “they’re burning cash.” Only the companies making silicon are raking it in.
There are constantly new techniques being developed to speed up inference or reduce model size post training. There’s about a hundred different levers to pull that play on inference cost, and some of them don’t have much of an impact on quality.
Yet all major players are still incapable of covering their costs and have to resort to all sorts of nasty accounting tricks to make it apear otherwise. How so?
Because of the massive investments into datacenters. Why is everyone so quick to drink the kool-aid. They are spending stupid amounts of money to capture the market and force everyone into a subscription service, not because it cost money to actually run the models. They are all switching their models to fine tuned quants after the first two weeks as well.
The open source community has found dozens of ways to lower costs, do you really think these big companies aren’t using the same tricks and haven’t developed even more advanced techniques?
It doesn’t matter what tricks they supposedly use afterwards, the data centets that are built need to run successfully or the bubble pops and then those companies will fall like lead. In other words for those data centers to be successfull the entire real economy has to spend crazy amounts of money on stuff that needs crazy amounts of compute.
Open AI and Anthropic would really need some good business numbers, right now. The claim that they are just deliberately making their business case much worse than it is, is insane.
The inference cost doesn’t actually drop in reality.
My comment was about this which is just completely wrong.
OpenAI is the scummiest company on earth but everyone is ready to believe them when they say shit like "our 20$ plan lets you run up the equivalent of a billion dollars in API fees. Giggles. It’s a good plan for you but not for us ;) "
The main thing bringing up costs is Sam Altman spending all the “inference” money on raw wafers just to strangle consumer GPU sales.
So in essence the price that the market will bare for the cost of AI usage is significantly lower than what the big AI companies would like it to be (in order to pay back their ever growing debts), which means there is a possibility they might never achieve profitability on their own (without some external/governmental strong-arming)
Yeah, I’d like to see the cost of sub-prime mortgage on that chart.
Extremely interesting… so the depreciation of older models is extreme, while new models are constantly presented. And all the while no AI company is making any profit. This whole story is bonkers
Hadn’t you heard? Some day, one of these things is gonna cure cancer. We all just gotta kill ourselves subsidizing it until then!
The catch is
the cost of a given level of AI performance
And more interestingly the article itself says this
And to this extent, when comparing price drops for AI to drops for other technologies for which we have price series, we are comparing apples and oranges.
Even then, they decided to make it the headline. This is just like LLM bros doing things they don’t know anything about. Absolute garbage.