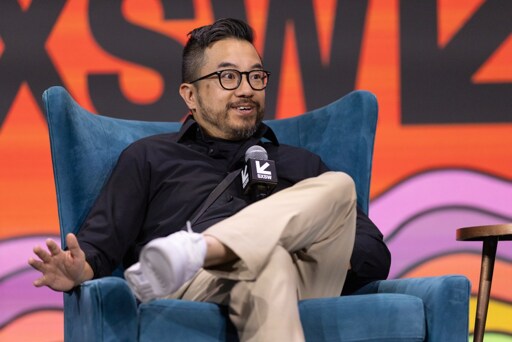
Tan wants smaller, American open-weight AI labs to use the same kind of training techniques on American frontier AI labs, giving the U.S. a more robust set of open-weight options that aren’t Chinese.
They’re all trained on copyleft data, so they should by all rights be open source. Distilling them into open weight models is the next best thing, I suppose.


They’re all trained on copyleft data, so they should by all rights be open source. Distilling them into open weight models is the next best thing, I suppose.